



How Much Does Generative AI Cost? Understanding Generative AI Pricing

There is no single price for generative AI. A small experiment may require only a managed tool, API usage, and light integration work. A production system with private data, permissions, evaluation, security, and ongoing support can require a much larger investment.
For most business projects, the useful question is not only “How much does the model cost?” It is also “What does the workflow around the model require?” This guide separates model usage, implementation, and operating costs so that teams can build a more realistic generative AI budget.
The Total Generative AI Cost Goes Beyond Model Fees
Generative AI cost has three main layers. The model or tool is only one part of the total budget.
| Cost layer | What it includes | How the cost usually behaves |
|---|---|---|
| Usage costs | Input and output tokens, requests, generated images or audio, embeddings, search calls, and other metered cloud services | Usually scales with traffic, output length, model choice, and service tier |
| Implementation costs | Discovery, UX design, data preparation, application engineering, integrations, access control, evaluation setup, testing, and release work | Usually rises with workflow complexity, data quality problems, integration depth, and reliability requirements |
| Operating costs | Monitoring, quality evaluation, security review, knowledge refresh, support, incident handling, maintenance, and cost governance | Usually rises as more users, data sources, models, and business-critical workflows enter production |
A simple writing assistant may need little beyond seats, onboarding, and a usage policy. A custom internal assistant may need identity integration, document permissions, retrieval, logging, evaluations, and human fallback.
The same foundation model can therefore sit inside two products with very different total costs. A low model rate does not guarantee a low system budget.
Generative AI Pricing Models And Their Trade-Offs
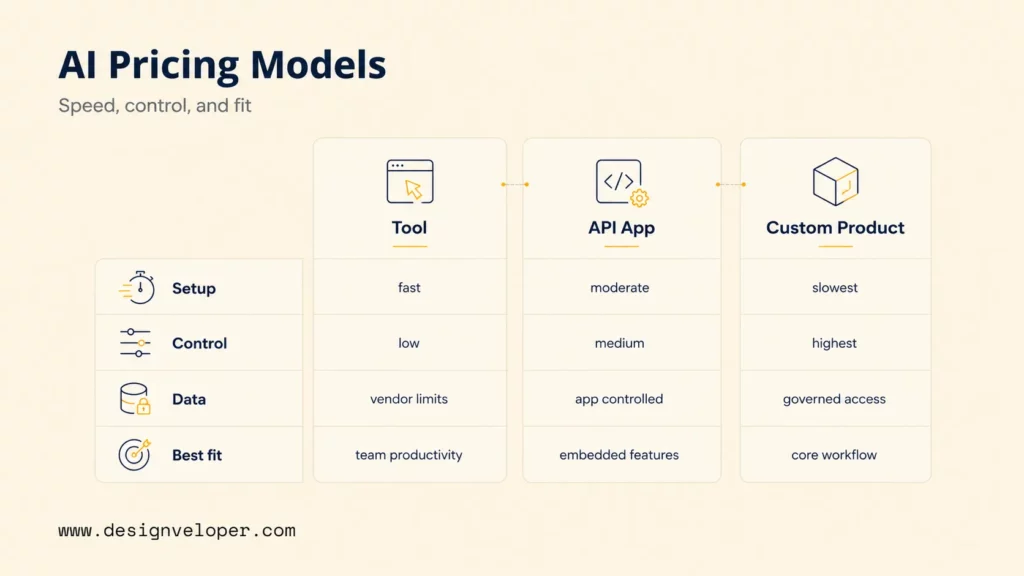
Most business teams start with one of three delivery models: an off-the-shelf AI tool, an API-based application, or a custom generative AI product.
| Option | Setup time | Control | Data handling | Recurring cost | Best fit |
|---|---|---|---|---|---|
| Off-the-shelf AI tool | Fast | Low to moderate | Limited to vendor features, policies, connectors, and admin controls | Subscription or per-seat | General writing, summaries, research, meetings, and productivity |
| API-based application | Moderate | Moderate to high | The application controls what is sent, stored, retrieved, and shown | Usage-based model fees plus infrastructure | Focused assistants, embedded AI features, document workflows, and automation |
| Custom generative AI product | Longest | Highest | Can add company-specific identity, permissions, retrieval, integrations, evaluation, and governance | Model or infrastructure usage plus engineering and operations | Business-critical or differentiated workflows that need deeper control |
The lowest model price does not guarantee the lowest system cost. The workflow around the model determines the wider budget.
Subscription And Off-The-Shelf AI Tools
Choose an off-the-shelf tool when the task is common, the vendor’s controls are acceptable, and the workflow does not need custom actions or permission logic.
Typical use cases include:
- Writing assistance.
- Meeting summaries.
- Basic research.
- Brainstorming.
- General team productivity.
- Drafting internal documents.
Before buying, verify admin and workspace controls, data retention and training policies, connector permissions, feature limits, model access, export options, enterprise support, and usage caps.
Add-ons or enterprise controls can also change the bill. A subscription may no longer be the simplest option when the workflow needs unsupported permissions, system actions, private knowledge, or strict auditability.
Generative AI API Costs
Generative AI API costs usually depend on input tokens, output tokens, model tier, and usage volume. Some providers also charge separately for tool calls, media generation, embeddings, search, or other services.
Longer prompts, larger retrieved contexts, and longer answers increase token consumption even when the number of requests stays unchanged.
If tokens are unfamiliar, our guide to AI tokens and token budgets explains how text becomes billable model input and output.
Monthly model cost = (monthly input tokens / 1,000,000 × input rate) + (monthly output tokens / 1,000,000 × output rate)
Checked August 25, 2026, OpenAI’s API pricing table for GPT-5.6 Terra lists the following Standard short-context text rates:
- Input: $2 per million tokens.
- Output: $12 per million tokens.
Standard long-context rates are higher:
- Input: $4 per million tokens.
- Output: $18 per million tokens.
Cached input, batch, flex, fast mode, regional processing, and other services can use different rates.
Provider and model choice can change the unit cost. Checked on the same date, Anthropic’s Claude Sonnet 5 pricing lists:
- Standard input: $2 per MTok.
- Standard output: $10 per MTok.
MTok means one million tokens. Quality, context size, caching, retries, latency, and tool use still affect the cost of a successful task.
Custom Generative AI Development Costs
Custom generative AI development costs cover the product around the model. Typical work starts with discovery, UX, data pipelines, and integrations. It may also cover identity and access management, permission-aware retrieval, evaluation datasets, human review, security controls, logging and observability, release support, and recovery when a model or connected system fails.
A workflow-connected product usually costs more than a basic API connection because it must handle real business rules. It needs to know who the user is, which data is allowed, which actions are permitted, and how results are checked.
If a knowledge assistant retrieves private policies, it must preserve source permissions. It should not expose every indexed document to every employee.
Published vendor benchmarks can provide a planning reference, but they are not universal quotes. Appinventiv’s 2026 generative AI development cost guide presents the following directional ranges:
| Complexity | Typical scope | Directional cost range | Indicative timeline |
|---|---|---|---|
| Basic | Single workflow, limited users, light integration | $40,000–$150,000 | 3–4 months |
| Moderate | Domain assistant, retrieval, integrations, and analytics | $150,000–$250,000 | 4–7 months |
| Advanced | Multi-use-case platform, governance, and reliability requirements | $250,000–$400,000+ | 7–12+ months |
These are one vendor’s planning ranges, not universal quotes or a Designveloper estimate. The actual budget depends on data readiness, integration depth, security requirements, quality targets, and operating scope.
The same source illustrates a five-month build with four delivery roles: an architect, backend engineer, frontend engineer, and QA/PM. This is an illustrative staffing example rather than a fixed team structure. A real project may also need data, security, FinOps, or domain specialists.
Our guide to AI app development costs explains how data readiness, integrations, risk, and operational scope can move an estimate beyond a simple feature benchmark.
How To Estimate The Cost Of Implementing Generative AI
The cost of implementing generative AI is easier to estimate when the team separates one-time delivery from ongoing operations.
Start with a specific user task. Then estimate real usage, map data and integrations, define quality controls, and compare pilot costs with production costs.
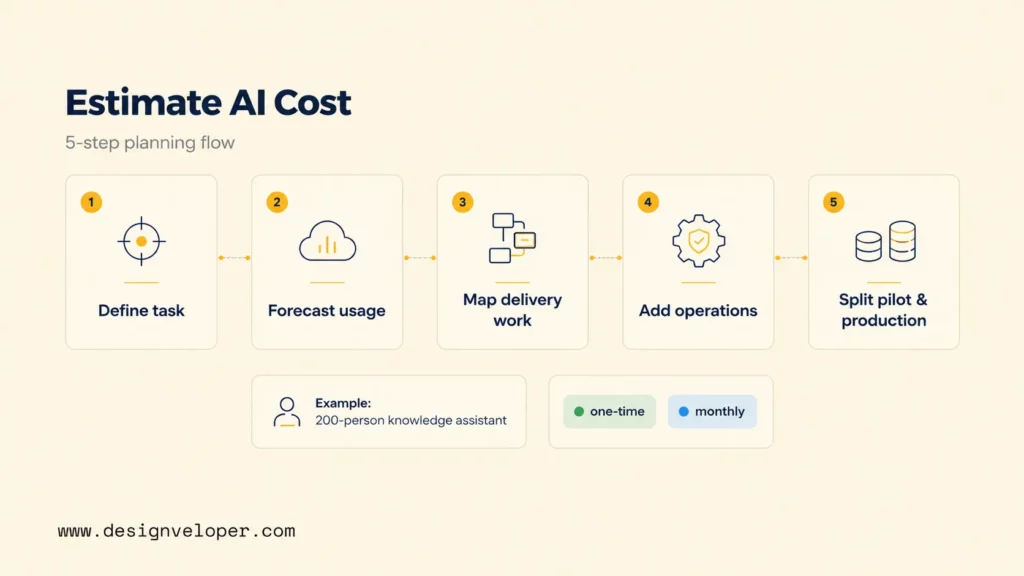
Before pricing the pilot, record these planning inputs:
- Task: Identify the user, business decision, expected answer quality, success threshold, and fallback path.
- Usage: Estimate active users, requests per user, input and output tokens, and peak concurrency.
- Delivery: List data sources, data preparation, identity, permissions, integrations, and security work.
- Operations: Include evaluation sets, testing, monitoring, support, refresh jobs, incident handling, and named ownership.
- Budget boundary: Separate one-time build costs from recurring model, cloud, support, and maintenance costs.
Consider an internal knowledge assistant available to 200 employees with controlled document access.
Assume:
- 80 employees use it on an average workday.
- Each employee sends 8 requests per day.
- There are 22 workdays per month.
- Each request averages 4,000 input tokens.
- Each request averages 700 output tokens.
This produces:
- 14,080 requests per month.
- 56.32 million input tokens.
- 9.856 million output tokens.
Using the GPT-5.6 Terra Standard short-context rates above:
- Input cost: $112.64.
- Output cost: $118.27.
- Total model-fee estimate: approximately $230.91 per month.
This is a model-fee estimate under the stated assumptions, not the total operating cost. It excludes embeddings, vector search, storage, identity services, monitoring, tool calls, support, engineering, security work, and higher-rate processing modes.
The one-time delivery estimate should cover document ingestion, permission-aware retrieval, UX, authentication, and integrations. Add evaluation sets, logging, testing, and release work.
The production budget should include recurring cloud services, model usage, monitoring, refresh jobs, incident handling, and a named owner. This separation gives a more useful answer to “How Much Does Generative AI Cost?” than simply multiplying seats by a subscription price.
The Biggest Drivers Of Generative AI Development Costs
The largest cost drivers are not identical for every product. Rank them by how strongly they change usage, engineering work, or operating risk.
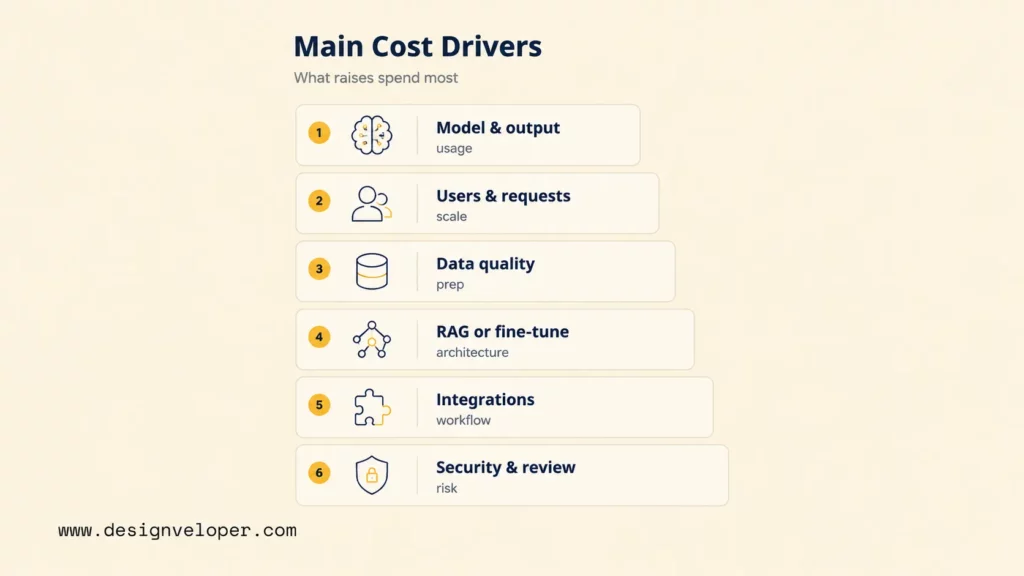
| Cost driver | What increases the cost | Planning control |
|---|---|---|
| Model usage | Larger models, longer outputs, and more frequent requests increase inference cost | Use the smallest capable model and set output limits |
| Traffic | More users, requests, and concurrent sessions increase inference and infrastructure load | Forecast adoption, peak concurrency, and growth |
| Data | More preparation, indexing, storage, and refresh work | Start with sources that materially affect answer quality |
| AI architecture | RAG, fine-tuning, tool calls, and orchestration add components to build and operate | Add architecture only when the workflow needs it |
| Integrations | More systems create more engineering effort and failure paths | Connect only the systems required for the validated task |
| Controls | Security, compliance, human review, and reliability requirements add testing and operational coverage | Match safeguards to data sensitivity and failure impact |
The AI architecture driver deserves special attention because extra context can create both value and cost.
Retrieval-augmented generation (RAG) can ground answers in private or current knowledge. It also adds ingestion, chunking, embeddings, search, permission filtering, refresh, and retrieval evaluation.
If the task does not need external knowledge, that stack may add complexity without enough benefit.
Risk requirements also change the budget. NIST’s Generative AI Profile for the AI Risk Management Framework is a voluntary companion to AI RMF 1.0. It helps organizations incorporate trustworthiness into the design, development, use, and evaluation of AI products, services, and systems.
Higher-impact workflows may therefore require more evidence, review, fallback handling, and operational coverage than a low-impact drafting aid.
Generative AI Budget Scenarios
Budget scenarios are more useful than universal price bands when the scope is still changing. Use the scenario matrix below to decide what must be validated before moving to the next level.
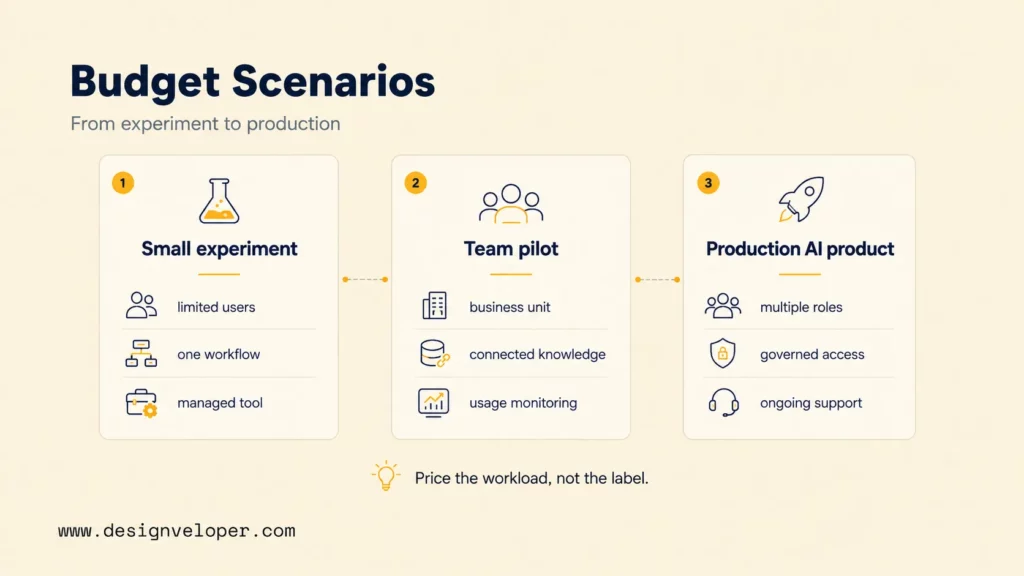
| Scenario | Scope | Main cost focus | Exit criteria |
|---|---|---|---|
| Small experiment | Limited users, one workflow, managed tool or API prototype | Seats or model usage, prompt design, light integration, and basic evaluation | The task shows measurable value and justifies deeper integration |
| Team pilot | One business unit, connected knowledge, evaluation criteria, and usage monitoring | Data preparation, retrieval, permissions, integration, monitoring, and support | Quality, adoption, permission behavior, cost per successful task, and failure handling meet the agreed targets |
| Production AI product | Multiple roles, governed access, integrations, reliability targets, and ongoing support | Scale, security, observability, incident response, continuous evaluation, and maintenance | The organization approves a sustainable operating model |
These are scope-based planning scenarios, not fixed price packages.
A small experiment can become expensive if it uses heavy media generation or premium models. A high-volume text workflow may still be economical when prompts are short and the architecture is simple.
Price the workload, not the label.
Lower Generative AI Operating Costs Without Reducing Value
The previous section identifies what creates cost. This section focuses on how to remove avoidable usage and infrastructure cost without weakening the workflow’s quality target.
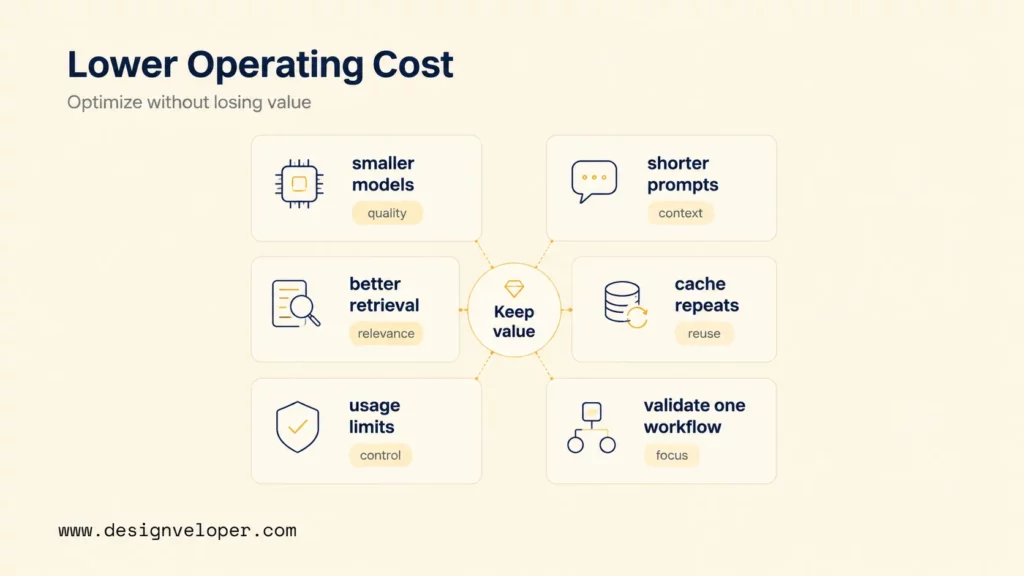
Use these tactics after establishing a baseline for quality, latency, and task completion:
- Route simple requests to smaller models. This can reduce inference cost, but the routing policy needs evaluation to prevent quality loss on harder tasks.
- Reduce unnecessary prompt length, context, and output. Shorter inputs lower cost, but removing useful instructions or evidence can increase errors and retries.
- Improve retrieval before increasing context limits. Better retrieval can send fewer, more relevant passages to the model. Poor retrieval can make a larger context window an expensive substitute for relevance.
- Cache repeated context and reusable outputs. Caching helps when prompts share stable content, but it adds little when every request is unique or the cache expires before reuse.
- Set usage limits and investigate unusual spend. Limits prevent uncontrolled growth, but they should not block legitimate peak demand without a fallback or approval path.
- Validate one high-value workflow before expanding. A narrow workflow makes quality and economics measurable. Expanding too early multiplies data, integration, and support costs before value is proven.
Current cloud platforms support several of these tactics. AWS’s Amazon Bedrock cost-optimization guidance identifies prompt caching and Intelligent Prompt Routing for supported workloads.
These tactics target repeated context or model selection. They do not replace required product controls, evaluation, or security review.
Plan Generative AI Spend Beyond The Pilot
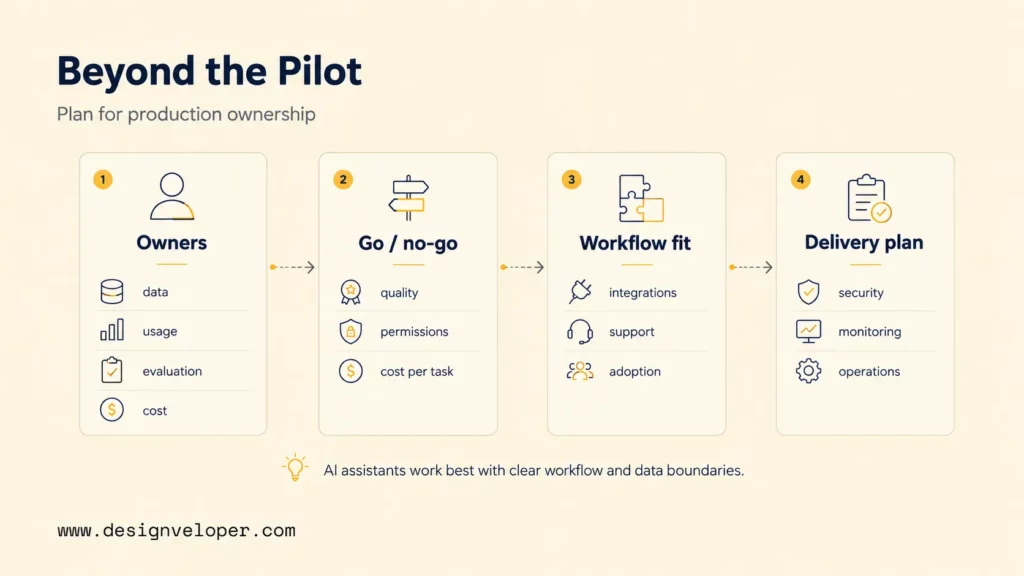
A viable production budget needs named owners, measurable go/no-go criteria, and recurring operating work. The initial build estimate is incomplete if nobody owns data quality, evaluation, security, usage, or cost after launch.
One-time delivery costs
- Discovery and feasibility assessment.
- UX and workflow design.
- Data preparation.
- Identity and access integration.
- Permission mapping.
- RAG or retrieval setup.
- Application engineering.
- Evaluation dataset creation.
- Testing and release work.
- Security and compliance review.
Recurring operating costs
- Model and API usage.
- Cloud infrastructure.
- Storage and search.
- Embeddings and refresh jobs.
- Monitoring and observability.
- Quality evaluation.
- Support.
- Incident response.
- Maintenance.
- Security review.
- Cost governance.
Assign responsibility before expansion:
- Product or platform owner: Tracks workflow value, adoption, and cost against the business outcome.
- Engineering or FinOps: Provides usage attribution, alerts, reliability data, and technical explanations for spend changes.
- Data owner: Approves source quality, access rules, and refresh requirements.
- Security or risk team: Defines controls for sensitive or high-impact workflows.
- Finance: Tracks budget variance and updates the forecast.
Go/no-go criteria should be observable. Useful criteria include an agreed answer-quality threshold, acceptable permission behavior, a maximum cost per successful task, sustainable support requirements, sufficient user adoption, acceptable latency and reliability, and a named owner for post-launch operations.
If the pilot misses these conditions, expanding the user count only makes the problem larger.
Generative AI Cost FAQs
How Can A Team Forecast Generative AI API Costs Before Launch?
Start with active users, requests per user, input and output token assumptions, peak concurrency, and expected growth. Run low-, expected-, and high-usage scenarios before launch. After the pilot, replace planning assumptions with observed traffic and token data.
Is A Custom Generative AI Application Cheaper Than An Off-The-Shelf Tool?
In many cases, an off-the-shelf tool is cheaper for general productivity because it avoids custom delivery work. A custom application can justify a higher upfront cost when the workflow needs deeper integration, permissions, private knowledge, or product control. Compare both options over the same usage period, quality target, and operating scope.
When Does RAG Add Meaningful Cost To A Generative AI Product?
RAG adds meaningful cost when the knowledge base is large, changes often, or requires permission-aware retrieval. It can improve answers that depend on private or current information, but it also adds ingestion, indexing, search, permissions, refresh, and evaluation work. If the base model can meet the task without private or current knowledge, the extra retrieval layer may not be justified.
Can Self-Hosted Models Lower Generative AI Operating Costs?
Potentially, under high and steady utilization. Self-hosting is a deployment choice rather than a fourth delivery model, and it may reduce variable model fees when provisioned compute stays well used.
The team then owns compute, serving, scaling, monitoring, patching, and incident response. Low or unpredictable traffic can leave capacity idle. Compare fully loaded infrastructure and staffing with a managed API under the same quality, compliance, and reliability target before deciding.
Who Should Own Generative AI Cost Monitoring After Launch?
One product or platform owner should have final accountability for generative AI cost monitoring. Engineering or FinOps can provide usage attribution and alerts, Finance can track budget variance, and data or security owners can manage their respective control areas.
The objective is to connect provider spend with adoption, quality, and workflow value rather than treating the provider invoice as the only measure of performance.
Teams that need to align AI scope with workflows, data access, and delivery planning can use our AI development services as a starting point. We can help map the workflow, define integration and permission boundaries, and plan evaluation and support around an AI assistant or other AI-powered software. The aim is a production plan with clear scope and operating ownership.
Also published on

Share post on




Related Articles


RAG Status In Project Management: Meaning, Colors, And Examples
RAG Status In Project Management: Meaning, Colors, And Examples Published September 09, 2026
What Is LangChain and Where Does It Fit in an AI Application?
What Is LangChain and Where Does It Fit in an AI Application? Published August 25, 2026
8 LangChain Use Cases For AI Products That Need More Than Prompts
8 LangChain Use Cases For AI Products That Need More Than Prompts Published August 25, 2026