



Git Concepts And Architecture: Objects, HEAD, Index & Workflow

KEY TAKEAWAYS:
- Stage the exact snapshot. The index selects what a commit records; learn how Git tracks project files before treating it as a file copy.
- Branches are references. A branch name points to a commit and moves when a new commit is made; it is not a second folder of files.
- Object IDs depend on the object format. SHA-1 is common, but Git also supports SHA-256 repositories; an ID is not a promise of global uniqueness.
- Commit and push are separate. A commit records work locally. A push shares it with a remote, which may then trigger a separate CI job.
Git concepts become easier when commands are tied to the state they change. Git’s architecture connects the files you edit, the content selected for a commit, and the saved project history. A separate object database stores snapshots and the links between commits. Confusion often starts when people treat a branch as a folder, assume a commit uploads code, or read the word “tree” as one thing everywhere. Following a file from edit to remote makes those boundaries clear and gives each Git command a practical role.
Git Architecture at a Glance
Git is a distributed version control system. Its day-to-day model has a working tree, an index, and a current commit identified by HEAD. Its storage model uses objects for file content, directory structure, commits, and tags, while references give human-readable names to commits.
These are related parts of one system, but they are not interchangeable:
- Working tree: the checked-out files you can inspect and edit.
- Index: the staged snapshot Git will use for the next commit.
- HEAD: the current position in the local commit history, usually through the active branch.
- Object database and references: the saved content and the names that lead to commits and tags.
A remote repository is another copy that Git can exchange commits with. GitHub and similar services host repositories and add collaboration features, but Git itself is the version control system.
Git Stores Project Snapshots as Objects
Git builds project history from objects. A commit points to a top-level tree for one project snapshot and links to its parent commit or commits. The tree records directory entries and points to file blobs or other trees.
The four Git object types are:
- Blob: stores a file’s content, without its filename.
- Tree: stores names, paths, modes, and references to blobs or nested trees. A tree object is a Git data structure, not the editable working tree.
- Commit: points to a project tree and records metadata, a message, and parent commit IDs.
- Annotated tag: stores a named marker and metadata that points to an object, often a release commit.
Git calculates an object ID from the object’s type, size, and content representation. SHA-1 is the common format in existing repositories, while Git also supports the SHA-256 object format. The Git hash-function transition notes describe the format change. Identical object representations produce the same ID in the same hash format, but a hash should not be described as a guaranteed globally unique identifier.
Git does not store a special “rename object.” It stores file content and tree entries in snapshots; tools can infer that a path changed by comparing snapshots. This is why a file can keep the same blob while its path changes, and why rename detection is a comparison result rather than a separate piece of history. The Git Book’s Git Objects chapter explains how blobs, trees, commits, and tags connect.
Git can also pack and compress objects to store or transfer them efficiently. A network operation does not always send only changed lines or whole files; Git negotiates which objects are needed and may send packed objects.
For a deeper dive:
- Hash Values (SHA-1) In Git: What You Need To Know
- Head Pointer in Git: What You Need To Know?
- Tree Data Structure: A Closer Look
The Three Work Areas: Working Tree, Index, and HEAD
The three-part model describes where a version of your project sits while you work. Git’s Reset Demystified chapter uses these areas to explain how changes move from an edit to a commit.
| Area | What it represents | Useful check |
|---|---|---|
| Working tree | Checked-out files, including tracked edits and untracked files | git status or git diff |
| Index | The content selected for the next commit | git diff --cached |
| HEAD | The current commit, usually reached through the active branch | git show --stat HEAD |
People call this the “three-tree” model, but the name is a mental model for three states. It does not mean all three are Git tree objects. In particular, the working tree is the files on disk, while a tree object is an object in the repository that records directory entries.
Working Tree: The Files You Are Editing
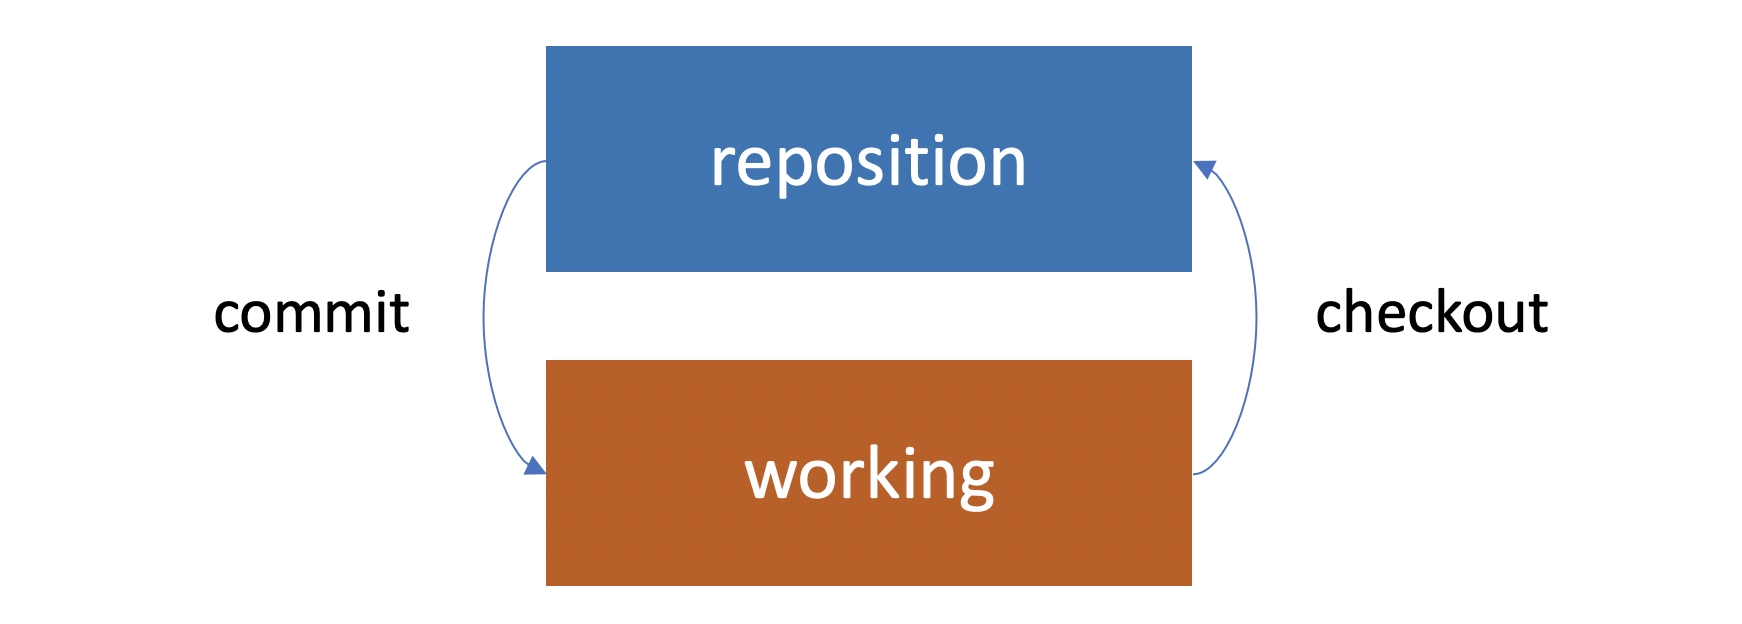
The working tree is the project content visible in your checkout. Editing a tracked file changes this area; creating a new file makes it untracked until you stage it. Git’s index and commit history do not change just because you saved a file in an editor.
git status reports which paths are modified, staged, or untracked. Ignore rules can keep generated files, local settings, or build output out of the normal workflow; see Git ignore rules for pattern details. Ignoring a file does not remove it from the working tree.
In a simplified two-state view, you compare the working files with the last committed snapshot. Git adds the index as a third state so you can select which changes belong together in the next commit.
Index: The Snapshot You Plan to Commit
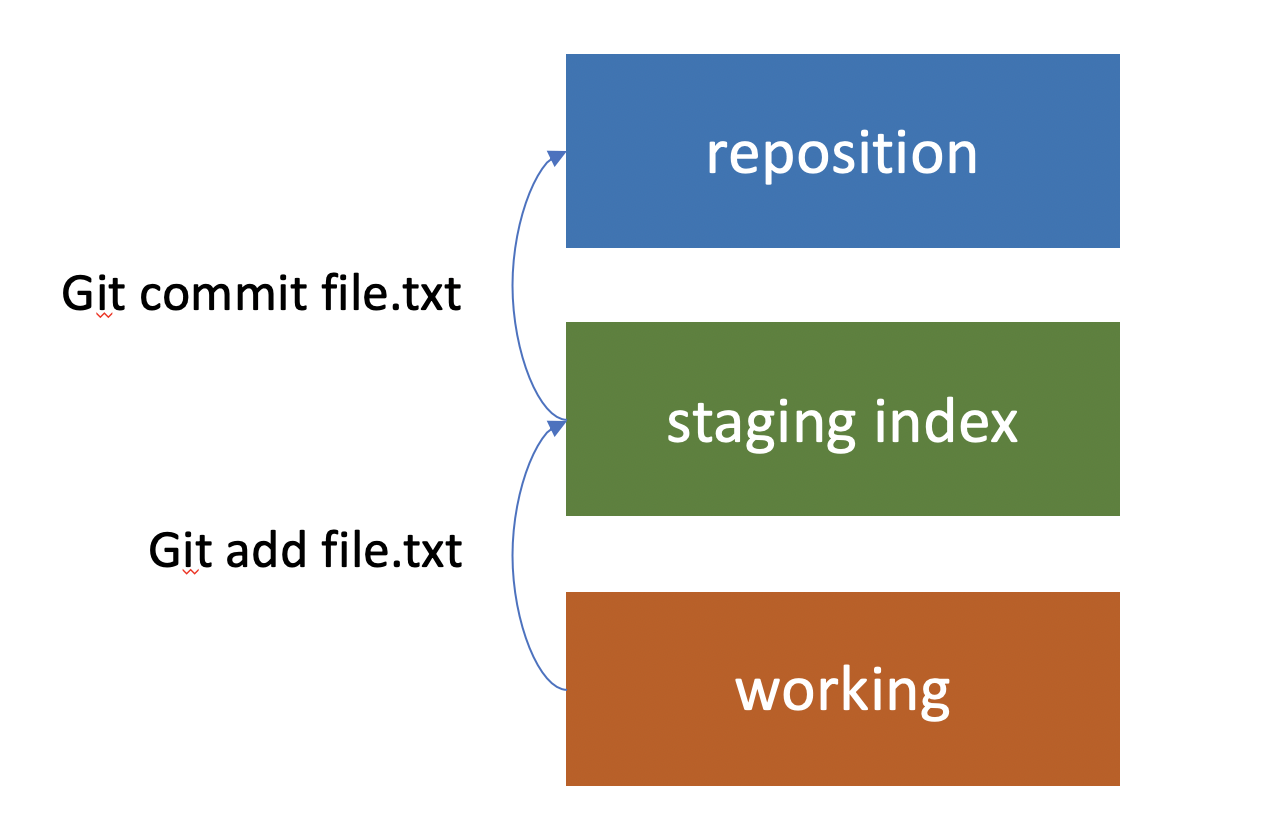
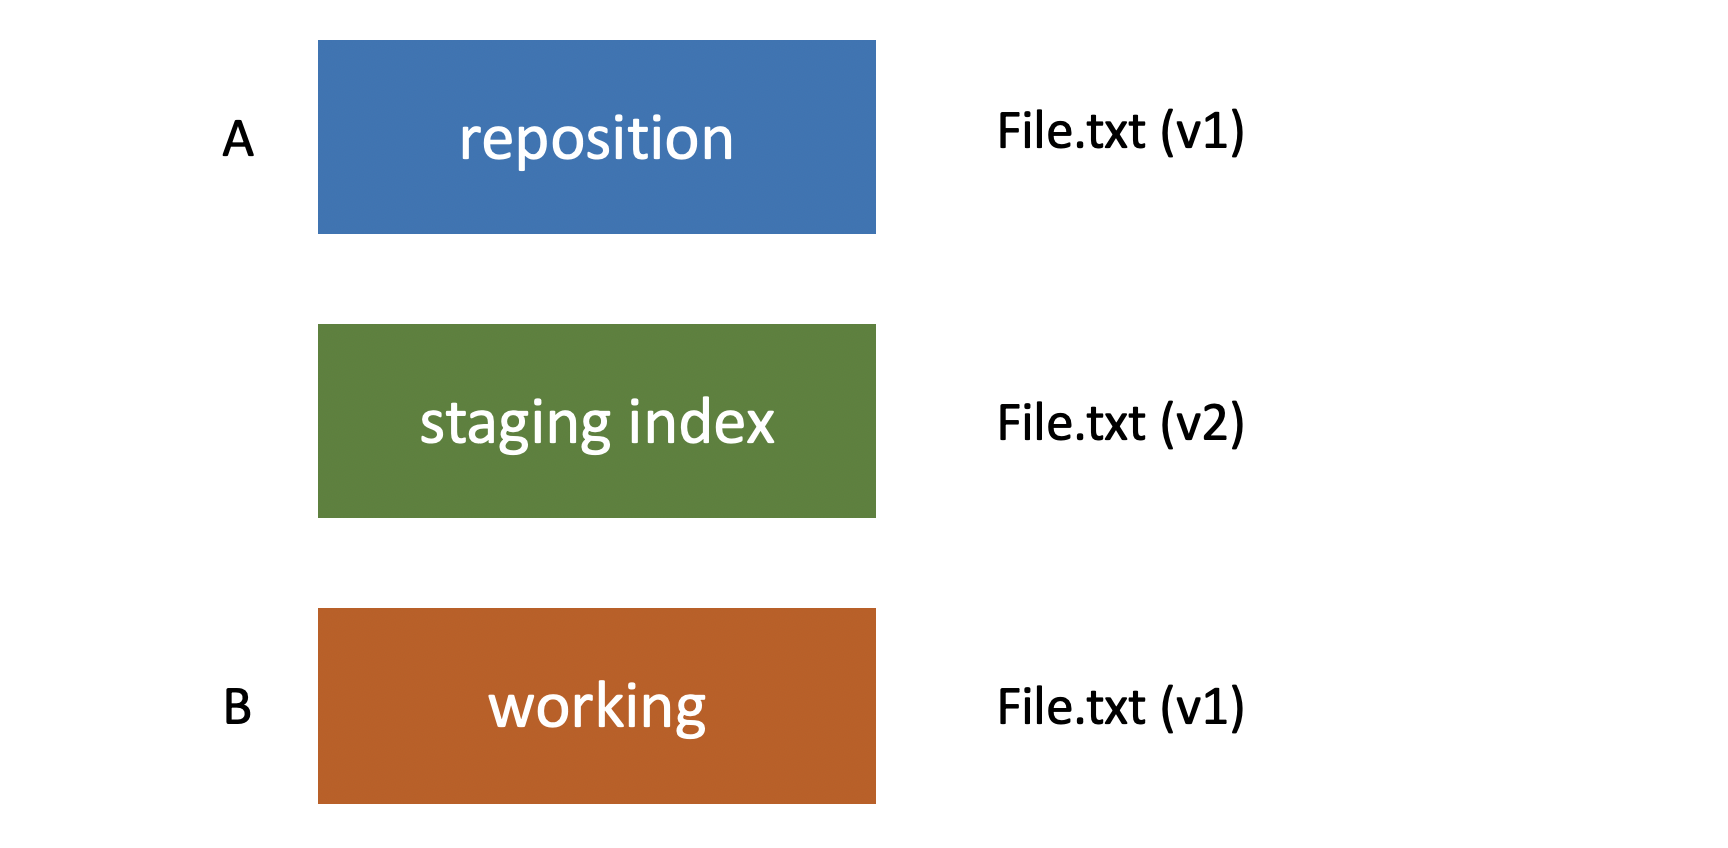
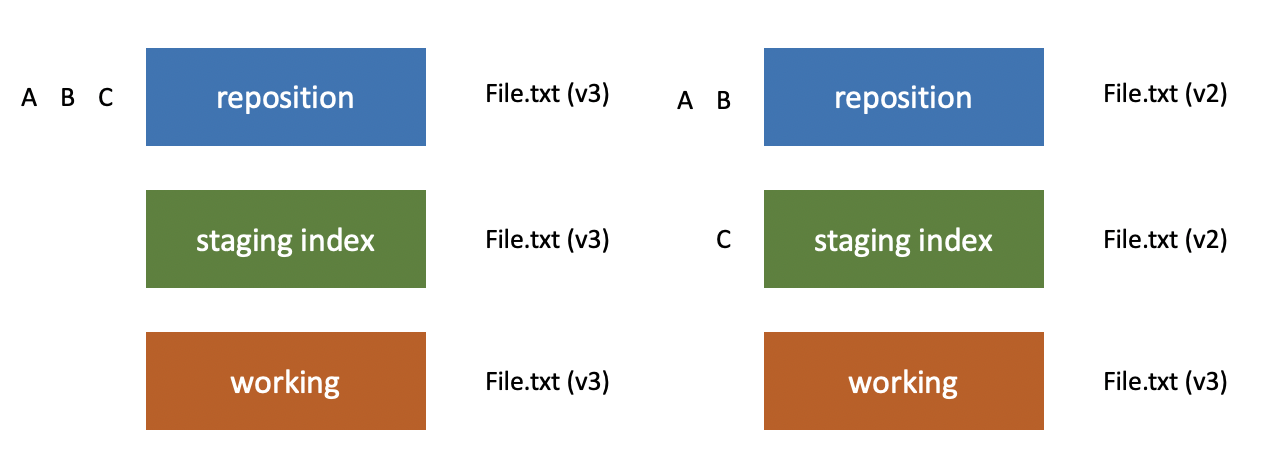
The index is Git’s staging area. When you run git add, Git records the selected version of a path in the index. Later edits to that file stay in the working tree until you stage them again.
This separation lets a developer edit two files but commit only one. For example, stage README.md, inspect the staged version, and leave an unrelated edit to app.py for another commit. You can also use git add -p to stage selected parts of a tracked file.
The index is not a queue of commands and it is not a second permanent repository. It is the exact proposed snapshot for the next commit. Reviewing it before committing helps prevent unrelated changes from being mixed together.
HEAD: The Current Position in History
HEAD identifies the current point in the local history. Most of the time it refers to the current branch, whose reference points to the latest commit on that branch. When you check out a commit directly, Git can enter detached-HEAD state and point HEAD at that commit instead.
The names working tree, index, and HEAD therefore answer different questions: what files are checked out, what content is staged, and which commit is the current base. The Git glossary defines terms such as branch, index, and reference.
In a normal checkout, the reference chain is HEAD to the branch name to a commit. Git compares the index with that commit when you review staged changes, so the three areas describe related states rather than three separate copies of the repository.
A Correct Git Workflow: Edit, Stage, Commit, Then Push
A basic Git workflow has separate local and remote steps. For a new file, stage it before committing; for an existing file, stage the version you want to record.
1. Check What Changed
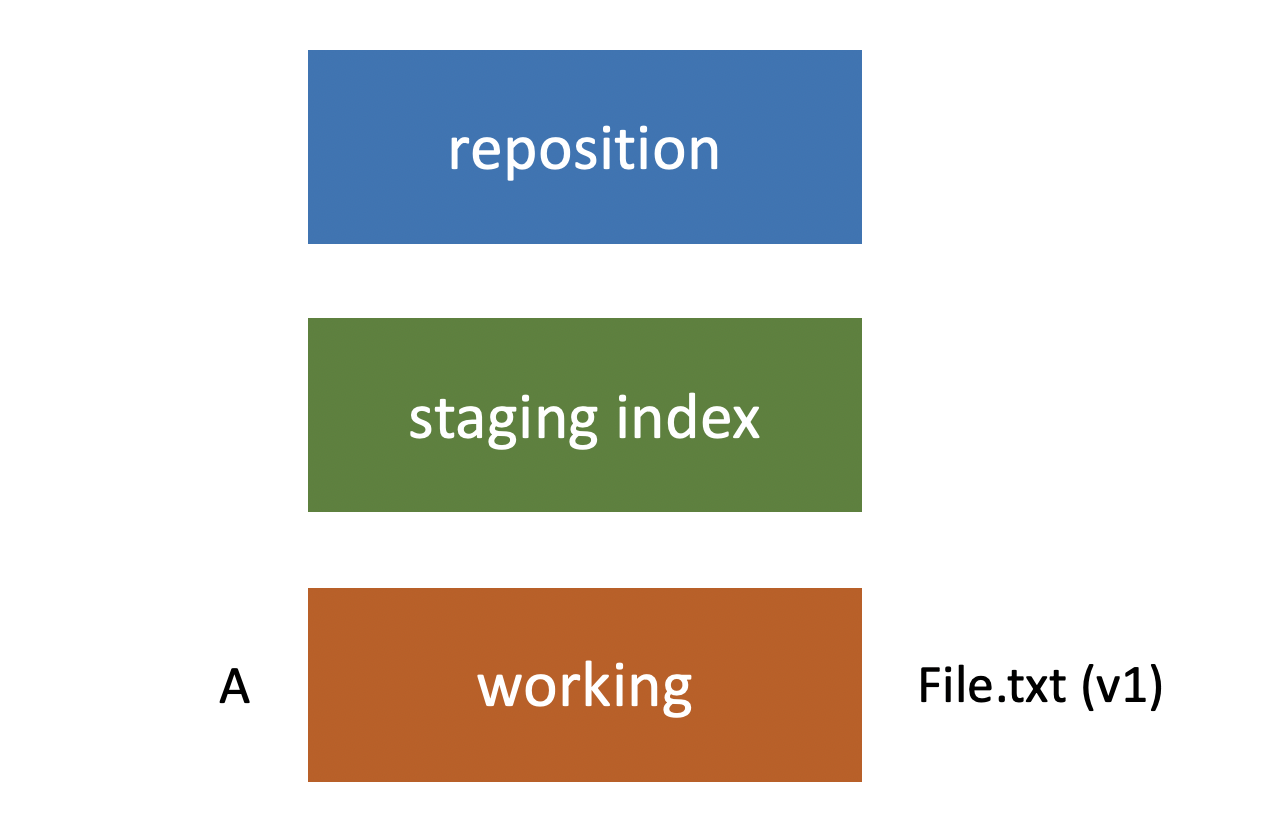
Run git status after editing. It shows tracked changes, staged content, and untracked files. For tracked files, git diff shows unstaged changes compared with the index.
Start from the status report instead of assuming every saved edit is ready for a commit. A new file is untracked, so Git will not include it until you add it.
2. Stage and Review the Selection
Use git add README.md to stage one file, or git add -p to select parts of a tracked file. A new file also needs git add; otherwise there is nothing staged for Git to commit.
Then run git diff --cached to compare the index with HEAD. If the output includes unrelated work, adjust the index before making the commit. The git add documentation describes how paths and selected content enter the index.
3. Commit the Staged Snapshot Locally
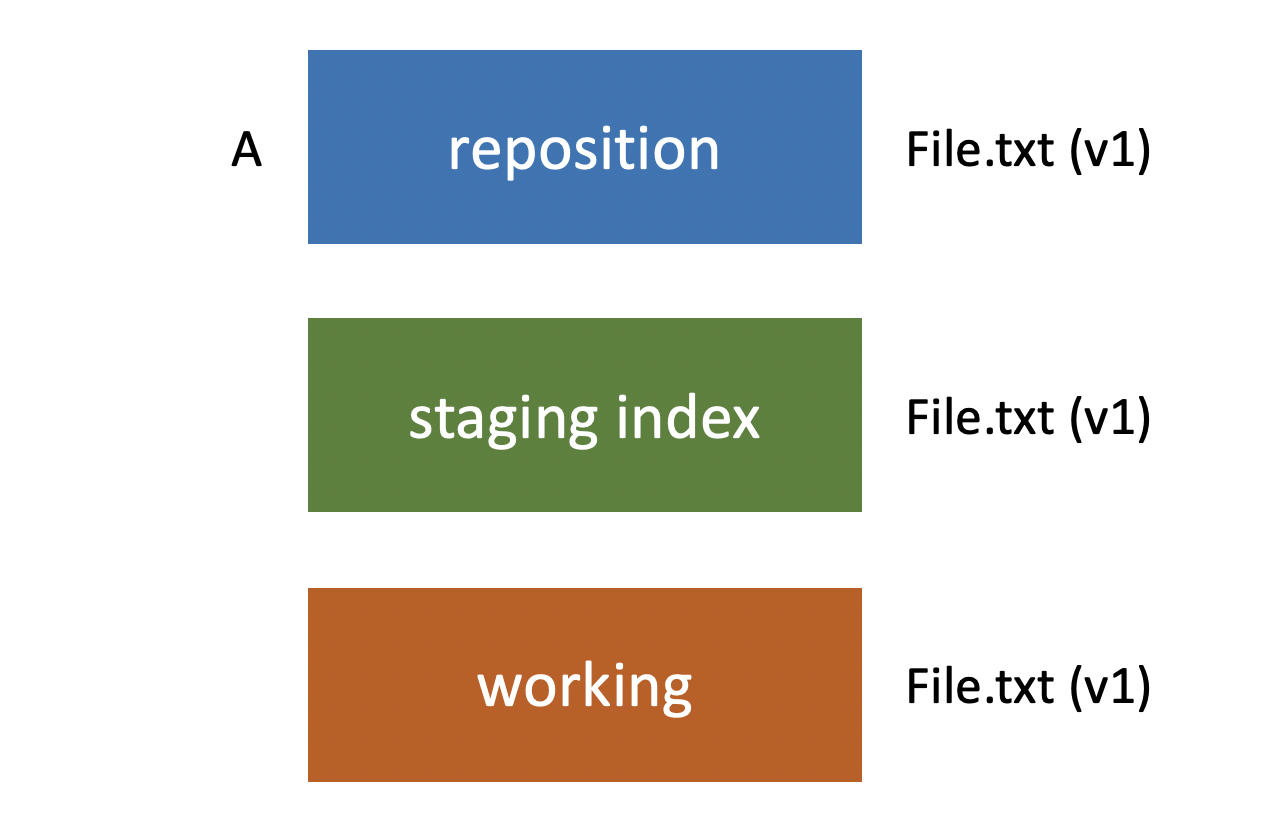
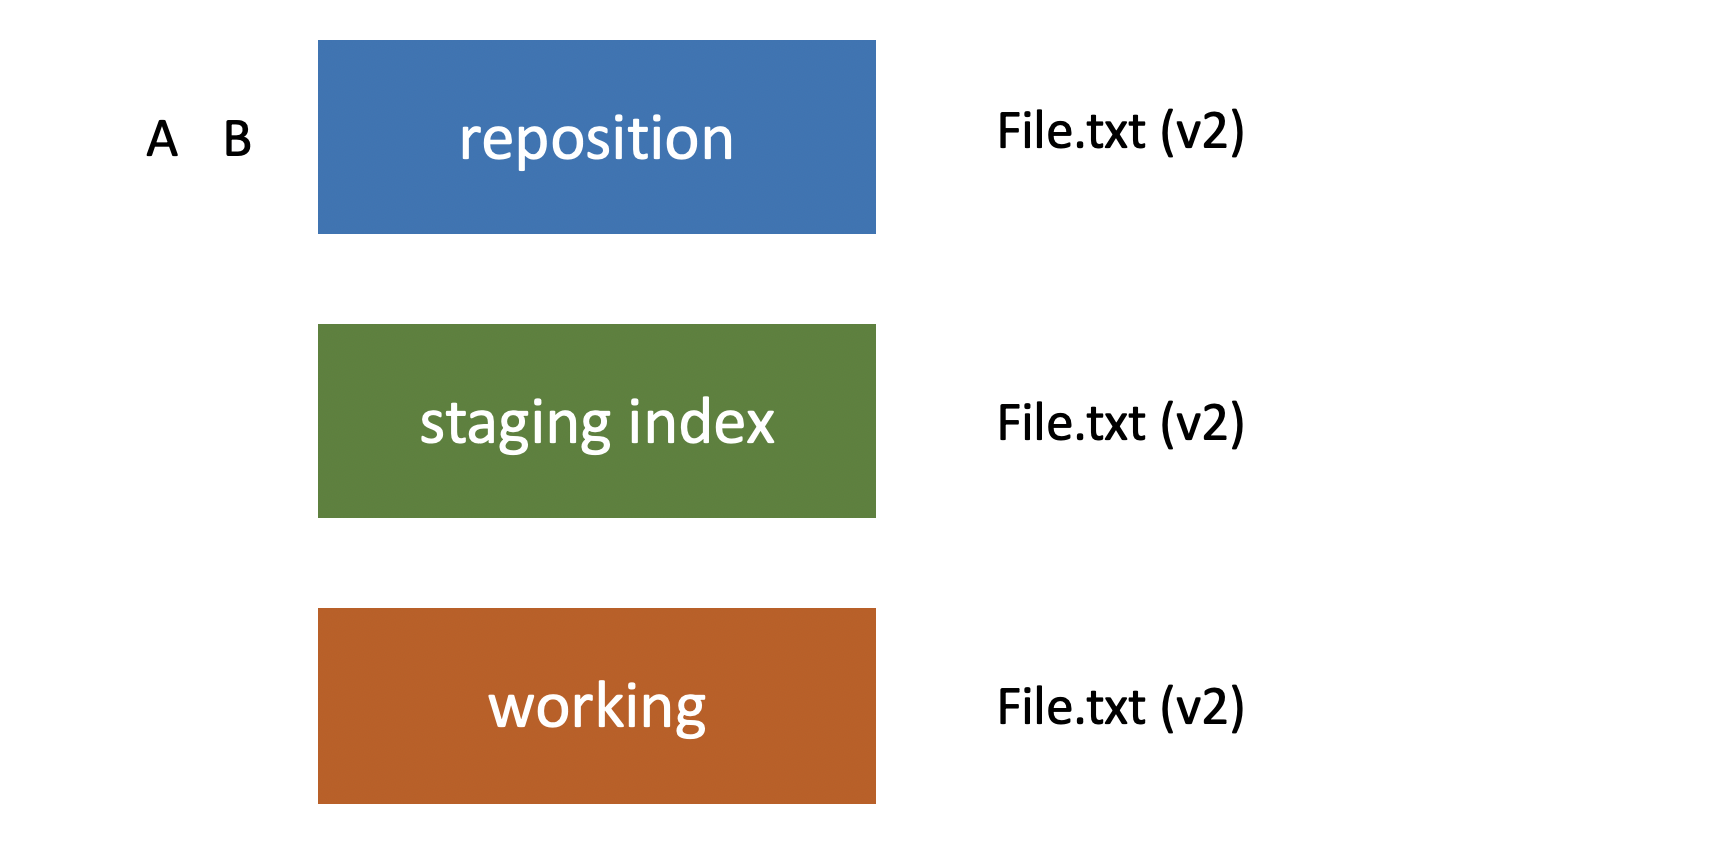
Run git commit -m "Clarify setup instructions" to create a local commit from the index. A commit has an ID and parent link, so it becomes part of the repository’s history. It does not upload the commit to GitHub or another server.
The commit records the staged snapshot, not every current edit in the working tree. If you change a file after staging it, that later edit is not part of the commit until you stage it again. See the official git commit documentation for the command’s behavior.
After the commit, git status can show whether other edits remain. A clear commit message says what changed, while the files and diff show the actual change.
4. Push Only When You Want to Share
Use git push origin main to send local commits to the configured remote named origin and update its main branch. Replace those names with the remote and branch used by your project.
Commit and push are different operations: the first saves a local point in history; the second asks a remote repository to receive commits and update a reference. Git may transfer packed objects the remote lacks, rather than sending a simple list of changed lines. Read the official git push documentation before changing remote or branch settings.
A successful local commit can exist even when the network is unavailable. The commit remains in your local repository and can be pushed later when the remote is reachable.
Branches, References, and Remotes
Branches and remotes help Git name and share commit history; neither replaces the working tree or index.
A Branch Is a Movable Reference
A local branch is a reference to a commit. When you make a new commit while that branch is checked out, the branch reference moves forward to the new commit. Git does not need to copy the whole project into a separate folder for every branch.
Because commits point to parent commits, branches share history until their paths diverge. Merging joins histories; rebasing creates a new sequence of commits on a different base. Those operations change commit relationships and references, while the working tree shows the checked-out result.
A Remote Is Another Repository, Not the Index
A remote is a named connection to another repository, often on a hosting service. A remote-tracking reference such as origin/main records the last known position of that remote branch; it is not the remote server itself.
git fetch downloads objects and updates remote-tracking references without merging those commits into the current branch. git pull fetches and then integrates remote changes according to the configured strategy. Knowing the difference helps you review incoming work before it changes your checked-out files.
Use git log --oneline --graph --decorate --all to inspect commits and references together. The output can show where local branches, remote-tracking branches, and HEAD sit in the history.
Git Is Part of DevOps, Not the CI/CD Runner
Git records and exchanges source history; a CI/CD platform performs automated build, test, or deployment work. A team can configure a push or pull-request event to start that external workflow, but Git does not run the build or deploy the application by itself.
For example, a developer can commit a change locally, push it to a shared branch, and let a configured DevOps pipeline run checks. The pipeline’s rules decide which tests run and what happens if one fails. The team still needs to review test results and protect production changes with suitable approvals.
This boundary matters in a practical Git workflow: version control gives the team a traceable change, while CI/CD adds checks and delivery actions around that change. The two work together, but they are separate systems with separate configuration and failure modes.
Related reading:
- What Is DevOps? The DevOps Lifecycle And How It Works
- DevOps Best Practices: 10 Ways To Improve Speed And Reliability
- Agile vs DevOps: Key Differences and How They Work Together
Git Concepts and Architecture: FAQs
Is a Git Tree Object the Same as the Working Tree?
No. A tree object stores directory entries and references to other Git objects. The working tree is the checked-out set of files you view and edit on disk.
Does Git Store Renames as Separate Objects?
No. Git stores file content and tree entries in snapshots. Rename detection compares snapshots and reports a likely move; it is not a distinct rename object.
Can You Commit to Git Without an Internet Connection?
Yes. A commit is recorded in the local repository. Internet access is needed only for operations that contact a remote, such as pushing or fetching.
Is Git the Same as GitHub?
No. Git is version control software. GitHub is a hosted service that stores Git repositories and adds tools for collaboration and automation.
Keep one sequence in mind: edit in the working tree, select content in the index, and record a local commit. Push only when that commit should reach a remote.
Also published on

Share post on




Related Articles


Why Learn JavaScript? Career Benefits, Uses, And Learning Path
Why Learn JavaScript? Career Benefits, Uses, And Learning Path Published October 21, 2026
Best JavaScript Frameworks For Web Development In 2026
Best JavaScript Frameworks For Web Development In 2026 Published October 19, 2026
How To Learn Rust? A Practical Roadmap For Beginners & Developers
How To Learn Rust? A Practical Roadmap For Beginners & Developers Published October 03, 2026