



What Is a Vector Database? How It Works, Use Cases & Limits

KEY TAKEAWAYS:
- A vector index finds nearby vectors; a database may also manage records, filters, updates, and query APIs.
- Existing relational databases and search engines may already provide vector or hybrid search; add a dedicated database only when the workload shows a separate need. Compare open-source vector database options after defining that workload.
- Approximate nearest-neighbor search can lower query work while missing some exact neighbors; measure recall and latency on your own queries.
- Metadata filters can narrow retrieval, but authorization must still be enforced for the signed-in user.
A vector database stores embeddings and retrieves records that sit near a query in vector space. That can surface relevant material even when wording differs, but similarity alone does not prove that content is accurate, current, or allowed for a user. The choice is architectural: vector search can sit inside a relational database, a search engine, or a dedicated service. The sections below follow one support RAG flow, compare these options by workload, and give a practical way to evaluate them.
What Is a Vector Database?
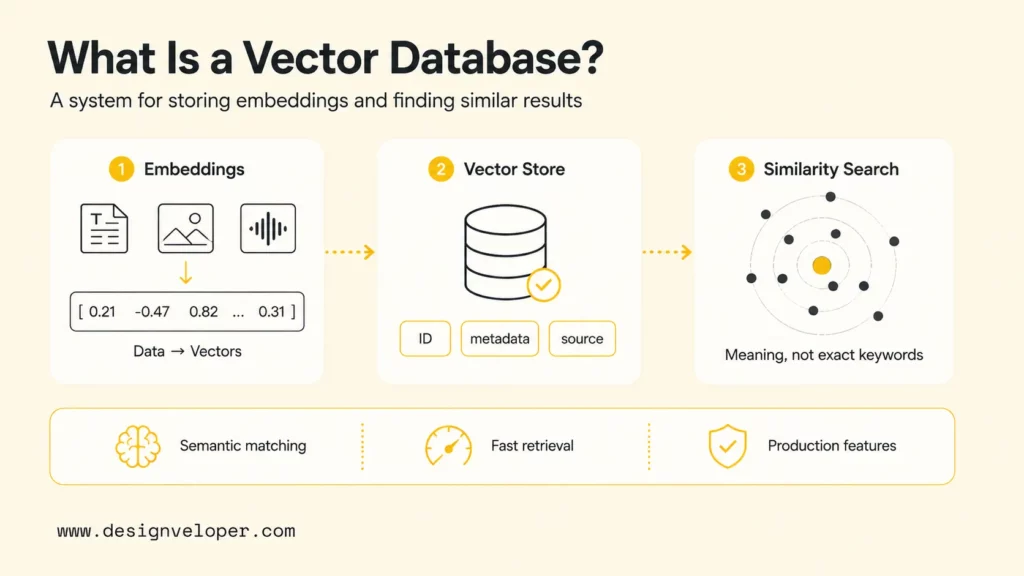
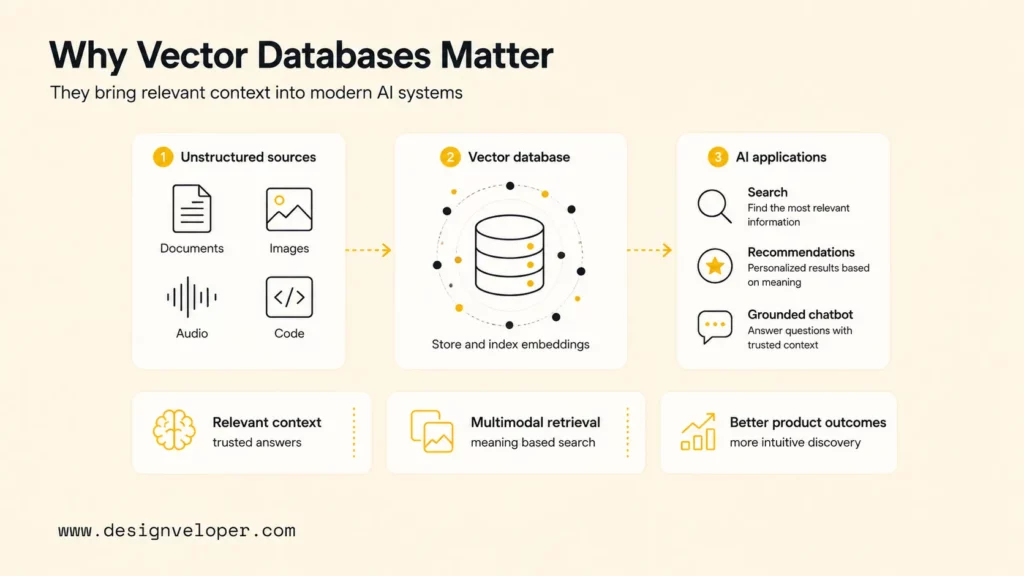
A vector database stores records that contain embeddings, builds or manages indexes for those vectors, and retrieves records near a query vector. An embedding model turns an item such as a document section or product image into a numerical representation. The database compares vectors and returns candidates; the application decides what those candidates mean and what to show the user.
An article titled “How to request a refund” may match the question “Can I get my money back?” even though the phrases share few words. The embedding brings them close in vector space; an application must still check whether that article applies to the user’s region, plan, and account.
A stored record commonly has an ID, an embedding, and metadata such as a source, category, timestamp, language, or tenant. Some systems keep the original text beside the vector; others store a pointer to a content system. Image, audio, and video search also depend on an embedding model that can represent the relevant media. A database does not make every data type searchable automatically.
Database versus index: a vector index is a data structure that finds nearby vectors. A vector database may also manage records, metadata, updates, filters, and query APIs around one or more indexes. Existing SQL and search systems can include vector indexes, so “vector database” does not always mean a separate server. For the broader data-layer comparison, see vector databases vs. traditional databases.
In retrieval-augmented generation (RAG), an application retrieves source passages and supplies selected context to a language model; the vector database is one retrieval component in that workflow.
The NVIDIA cuVS explanation draws this boundary: an index searches for neighbors; a data service may also manage records, metadata, and queries.
Related reading:
- What Is Generative AI? How It Works, Examples And Business Impact
- What Is A Chatbot? Real Uses, How It Works, And What It Can Do
- RAG Pipeline Diagram: Components, Workflow, And Production Design
Vector Search in Relational Databases, Search Engines, and Dedicated Systems
These systems are not mutually exclusive categories: the right comparison is which workload each one handles and how vector retrieval fits the rest of the application. Relational databases, search engines, and dedicated vector databases can all support some form of similarity search, but their query models, operations, and integration points differ. Use the workload matrix below to decide which layer you need; for dedicated-product options, compare ChromaDB alternatives and Chroma vs. FAISS vs. Pinecone.
| System or workload | Retrieval role | When it may fit | What to test |
|---|---|---|---|
| Relational database with a vector extension | Combines transactions, joins, exact filters, and vector similarity in the existing data system. pgvector adds vector types and similarity search to PostgreSQL. | Application records and embeddings share a lifecycle, and the existing database can meet query and filtering needs. | Filtered recall, index behavior, update load, query plans, and latency beside normal transactions. |
| Search engine with vector support | Combines lexical relevance, facets or filters, and dense-vector retrieval; a hybrid query can use both exact terms and semantic similarity. See Elasticsearch kNN documentation. | The product already depends on full-text search, ranking, and content filters. | How lexical and vector scores are combined, how ingestion stays current, and how filters change result counts. |
| Dedicated vector database | Focuses on storing, indexing, and querying embeddings, often with product-specific filtering and operational features. | Measured scale, latency, isolation, filtering, or service requirements exceed what the current data platform can provide. | Data synchronization, access controls, backups, monitoring, cost, availability, and migration effort. |
A useful architecture can keep customer records and transactions in SQL while using a vector index for semantic candidates. A search platform may combine keyword and vector scores in one query. The right split depends on retrieval, filtering, integration, and operational requirements.
Suppose a user asks to cancel a trial. Vector retrieval may surface a policy that says “end a subscription.” Use structured or lexical lookup for exact plan codes and renewal dates. Combine the methods when a question needs both semantic and exact matches.
How Do Vector Databases Work?
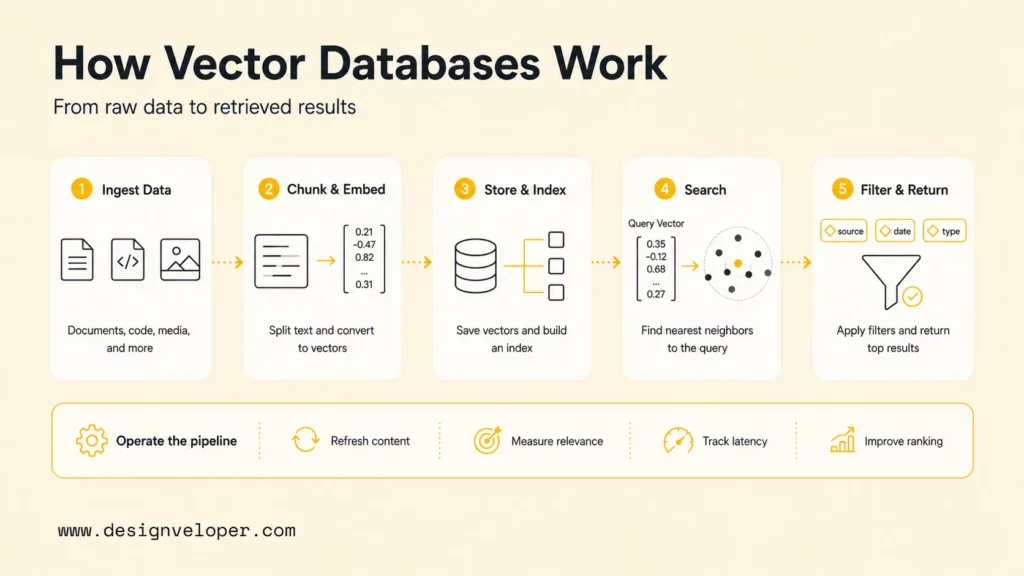
A typical retrieval flow converts content into compatible vectors, stores the vectors with record metadata, searches an index, and returns candidates for the application to use. Each stage affects relevance and operating cost, so teams should test the full path rather than judging the database by a single similarity query.
Create Compatible Embeddings
An embedding model converts source content into a vector. For text retrieval, teams often split long documents into sections before embedding so that each stored record has a focused topic and a stable source reference. Large chunks can mix unrelated details; very small chunks can lose the context needed to answer a real question.
Document and query vectors must use compatible models and dimensions. If the model or settings change, follow the provider’s compatibility guidance. Re-embed records when old and new vectors cannot be compared safely. For a knowledge-grounded bot, the guide to train a chatbot with your own data shows one path from source material to retrievable answers.
Store Records and Choose an Index
Store each vector with an ID and enough metadata to locate the source and apply the intended filters. The source text can live in the vector system or in a separate document store. In either design, keep a stable key between the returned vector record and the authoritative content so the application can fetch the right version.
Exact nearest-neighbor search compares a query with every eligible vector. Approximate nearest-neighbor (ANN) search uses an index to examine fewer candidates and reduce work on larger collections, but it can miss some of the exact nearest results. Google Cloud’s vector-search documentation describes this speed-versus-recall trade-off. An index can improve performance, but the gain depends on the workload and configuration.
Embed a Query and Rank Candidate Matches
The application embeds the user’s query with the compatible query model, then asks the index for the nearest records. A distance or similarity measure—such as cosine similarity, dot product, or Euclidean distance—orders those candidates. The model’s training setup and vector normalization affect which measure is appropriate, so raw scores from different models or metrics should not be treated as directly comparable.
The top results are candidates for a later step, not a confidence score that an answer is correct. In semantic search, the application may display ranked documents. In RAG, it may send a small set of retrieved passages and their source identifiers to a language model. If the query contains an exact identifier, combine vector retrieval with keyword or structured search rather than expecting embeddings to replace every lookup. For more complex pipelines, advanced RAG techniques can add lexical retrieval, reranking, and context selection around vector search.
Filter Results and Enforce Access Separately
Metadata filters can narrow the search to a language, product, region, tenant, or document status. A pre-filter may restrict the eligible records before approximate search; a post-filter may narrow a ranked result set afterward. These approaches can return different numbers of results and affect recall, especially when the filter is selective. The Elastic filtered kNN search documentation is one documented example of why filter placement matters.
A filter is not, by itself, authorization. Derive access from the authenticated user’s current identity and enforce it on every retrieval path before returning content. Test that missing or stale tenant metadata cannot expose a record, and verify that source links and the final generated answer respect the same permissions. Product teams should carry those checks through AI chatbot integration with account and helpdesk systems.
Related reading:
- How To Build A RAG System: Step-By-Step (New Guide)
- Build A RAG Agent With LangChain: Step-By-Step Tutorial
- RAG Best Practices Start Before Your Model Generates An Answer
Common Vector Database Use Cases
A useful design names the input, retrieval action, result, and the checks that keep it relevant and safe. The support example below applies that pattern to a refund question.
RAG for Knowledge and Support
For a support chatbot, imagine a user asking whether a recently renewed subscription can be refunded. The system can search approved refund-policy sections by meaning, then let the application verify the user’s plan, region, and account status before it uses a passage. The database helps find candidate text; the support application remains responsible for permissions and the final answer.
This is an illustrative retrieval design, not a measured production result. Teams comparing retrieval with model adaptation can review the RAG versus fine-tuning trade-off.
- Prepare the knowledge base. Split approved policy documents into sections, retain a stable document ID and revision date, and generate embeddings with the model selected for both document and query retrieval.
- Apply the user’s context. Embed the question and search only records that match the user’s tenant, product, and locale. Separately check identity and document access against the authoritative permission service.
- Ground the response. Pass the permitted passages and source IDs to the answer model. Use lexical search alongside vectors for policy numbers, product codes, and exact dates. Return source links, or hand off to a person if no suitable passage remains.
- Evaluate the retrieval. Use a set of representative support questions with human-labeled relevant sections. Measure whether the right passages appear in the top results, verify filtered queries do not leak content, and track latency under expected load.
Semantic Search and Recommendations
A catalog can embed product titles and descriptions so “light jacket for wet weather” retrieves items labeled “water-resistant shells.” It can also surface products similar to one a user viewed. Apply exact rules for stock, size, region, price, or eligibility before showing results.
Vector similarity is a way to find candidates, not a decision that a result should be shown. Track user-relevant measures such as whether a suitable item appears in the top results, and inspect cases where semantic matches violate a hard business constraint.
Image and Multimodal Retrieval
A media library can retrieve visually similar images or connect a text query with images when its embedding model supports both modalities in a compatible space. Teams should verify the model’s supported inputs, image preprocessing, language coverage, and index behavior. A database that stores vectors does not create a cross-modal embedding model or guarantee that visual similarity matches a user’s intent.
Related reading:
- Top 10 Retrieval-Augmented Generation (RAG) Examples By Industry
- How To Build A RAG Chatbot: Steps, Code & Best Practices
- AI Chatbot Development: Types, Process, Costs, And Use Cases
Benefits, Limits, and When to Use a Vector Database
A vector database can make semantic retrieval easier to operate when the surrounding system needs indexed search, filters, updates, and a query service. It does not make answers accurate by itself, ensure that source material is current, or replace lexical search, structured queries, or permission checks.
- Semantic retrieval: can find related content when wording differs, but quality depends on the embedding model, chunks, corpus, and query.
- Approximate search: can reduce search work at scale, but teams must decide how much recall loss is acceptable for the task.
- Metadata filters: can focus candidates on a product or region, but selective filters can change result counts and must not stand in for authorization.
- Multimodal search: can connect supported input types when a compatible model and retrieval pipeline exist; it is not a default feature of every system.
Start with the system you already operate when it meets measured requirements for filtering, latency, and operations. Evaluate a dedicated vector database if the current platform misses a defined need. Run the same queries on both options and compare retrieval quality, latency, filter correctness, synchronization work, and operating cost. Vector retrieval supplies external knowledge; chatbot memory tracks conversational state. They can work together, but one does not replace the other; see the guide to AI chatbot memory.
Also published on

Share post on




Related Articles


AI Agent Governance: How To Manage Agents In Production
AI Agent Governance: How To Manage Agents In Production Published November 01, 2026
AI Agents vs Agentic AI: Differences From Execution to Autonomy
AI Agents vs Agentic AI: Differences From Execution to Autonomy Published October 30, 2026
Best AI Trading Bots For Crypto & Stocks In 2026 (We Tested Them All)
Best AI Trading Bots For Crypto & Stocks In 2026 (We Tested Them All) Published October 30, 2026