



RAG Vs. Fine-Tuning: Choose The Right Approach For Your LLM Apps

Choose retrieval-augmented generation (RAG) when your LLM app needs current or private knowledge. Choose fine-tuning when it needs to perform a stable task or follow a response pattern more consistently. Start with a clear prompt and representative user tasks. Then identify whether the failure comes from missing knowledge, inconsistent behavior, or both. Combine the approaches only if tests show that each solves a separate problem. Base the RAG vs fine-tuning decision on answer quality, cost, latency, and maintenance – not on a fixed rule.
What Is The Difference Between RAG And Fine-Tuning?
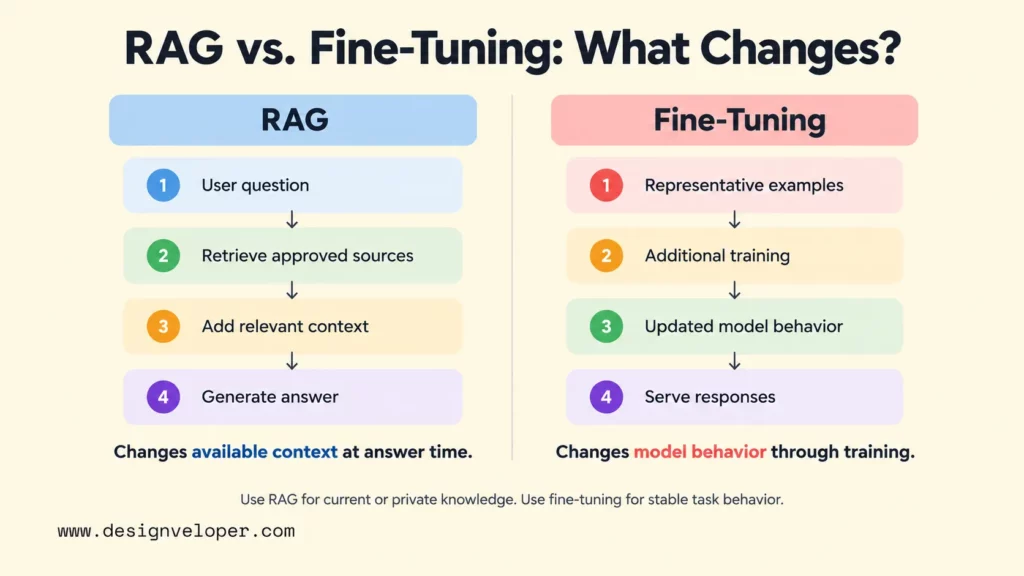
The key difference is what changes. RAG changes the information available to a model when it answers. Fine-tuning changes the model’s parameters through additional training. Neither approach automatically makes an LLM accurate, and neither replaces the need to test the actual application.
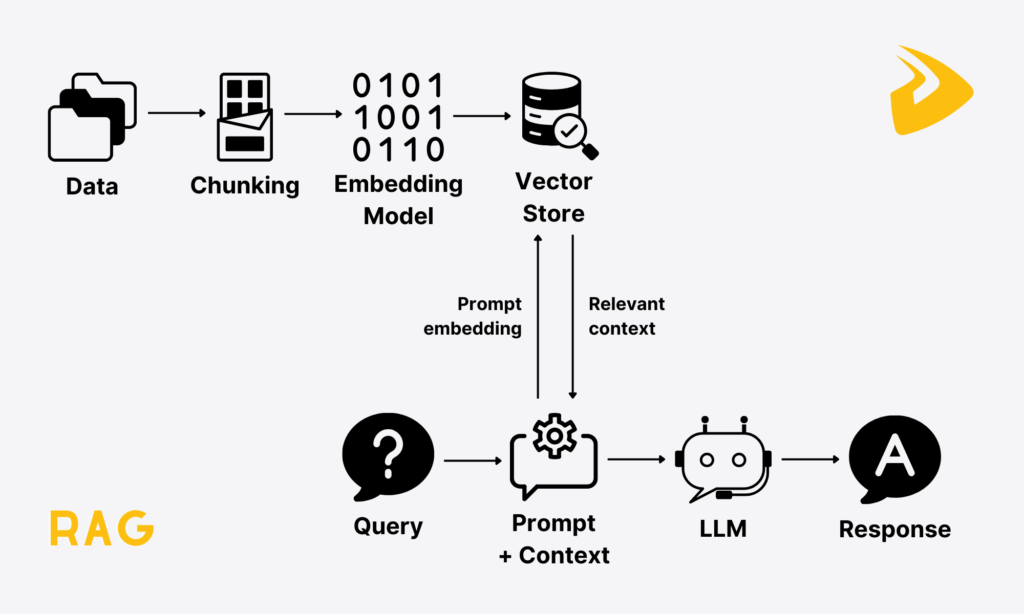
In a typical RAG system, the app searches approved content, selects useful passages, and adds them to the model’s prompt. The model then generates an answer using that context. An index helps the system search documents efficiently. It can support keyword, vector, or combined search. For a deeper explanation of these parts, see our guide to retrieval-augmented generation.
Fine-tuning works earlier in the process. A team prepares task-specific examples, runs an available training method, and evaluates the resulting model. For example, a support team might train a model to assign tickets to approved categories. Its training examples teach a repeatable mapping from incoming requests to labels. They do not give the deployed model a live connection to the latest support policy.
AWS’s comparison of RAG and fine-tuning makes the same practical distinction. It recommends starting with retrieval for question answering over custom documents, while noting that a trained model can support specialized tasks. The table below translates those differences into planning questions.
| Decision factor | RAG | Fine-tuning |
|---|---|---|
| Primary purpose | Supply relevant outside knowledge for each request. | Improve learned task behavior or response patterns. |
| Data updates | Refresh approved sources and the retrieval index; no model retraining is required for source changes. | Changing learned behavior or knowledge may require new examples and another training run. |
| Source traceability | Can show retrieved source records if the app stores and displays them correctly. | Does not inherently identify which training example supports a response. |
| Access control and governance | Filter approved content by the requesting user’s permissions before generation. The application must enforce these checks. | Fine-tuning does not authorize runtime data access. Control training-data use, retention, and provider settings separately. |
| Initial setup | Prepare sources, retrieval, access rules, prompt integration, and evaluation. | Prepare representative examples, a supported training job, and evaluation. |
| Ongoing costs | Maintain ingestion and search; pay for retrieval and potentially longer model inputs. | Pay for training, model serving, evaluation, and future retraining as needed. |
| Latency | Search adds work before generation; extra context can add model time. | May shorten prompts, but serving speed depends on the trained model and deployment. |
The cost and speed rows are trade-offs, not fixed winners. A small knowledge base with simple search can be inexpensive, while an elaborate retrieval pipeline may cost more. A fine-tuned model may need shorter prompts, but training and hosting can outweigh that saving. Compare the complete workflow at your expected traffic level rather than assuming one technique is always cheaper.
Use RAG When You Need Current, Source-Grounded Knowledge
RAG is the stronger starting choice when an answer must depend on information outside the model. This often means product details that change, private company rules, or technical documents that users need to inspect. The app can retrieve a newer source without training a new model, provided its content pipeline has actually been refreshed.
A finance assistant shows why private, changing data requires careful retrieval. Our public Song Nhi finance-assistant project describes a chat-based product that records expenses and answers spending questions. The page does not identify its model architecture. In a hypothetical RAG design, the app could retrieve only the signed-in user’s authorized transaction records and pass verified totals to the model for an explanation. A database should calculate exact totals rather than ask an LLM to guess them from text. Fine-tuning might improve stable expense categories, but it would not supply live transactions or enforce access rights. This architecture is illustrative, not a claim about Song Nhi’s implementation.
The retrieval step has its own prerequisites. Someone must own the source documents, decide which versions are valid, and keep the searchable index up to date. The app also needs to filter what each user may access before passing text to the model. Otherwise, a source-grounded response can still expose a document the user was not allowed to see. Microsoft’s RAG and indexes documentation identifies access control, source preparation, and retrieval quality as core implementation concerns.
Showing a source link also requires deliberate design. The system should preserve a document identifier or URL with each retrieved passage. It must then connect the displayed reference to the statement it supports. A plausible-looking citation is not proof of a correct answer. If retrieval misses an exception in a policy, the model can confidently give the wrong instruction even while citing a related document.
That is why a useful RAG test checks retrieval separately from generation. First ask whether the right passage appeared among the results. Then ask whether the model used it faithfully and answered the question. If the source was never retrieved, rewriting the prompt may not repair the main fault. Our step-by-step RAG build guide covers how to prepare sources, create an index, connect retrieval, and test the full response path.
RAG is less useful when the app has no dependable source to retrieve. It also may struggle with questions that require reading most of a long document rather than a few relevant passages. In those cases, test a longer-context workflow or a different document-processing method before adding a complicated retrieval layer.
Use Fine-Tuning When You Need Consistent Task Behavior
Fine-tuning is worth testing when a capable base model still performs a defined task inconsistently. The task might involve assigning categories, using specialized terminology, or following a strict response pattern across many requests. The intended result is a behavior you can measure, not a general promise that the model will become smarter.
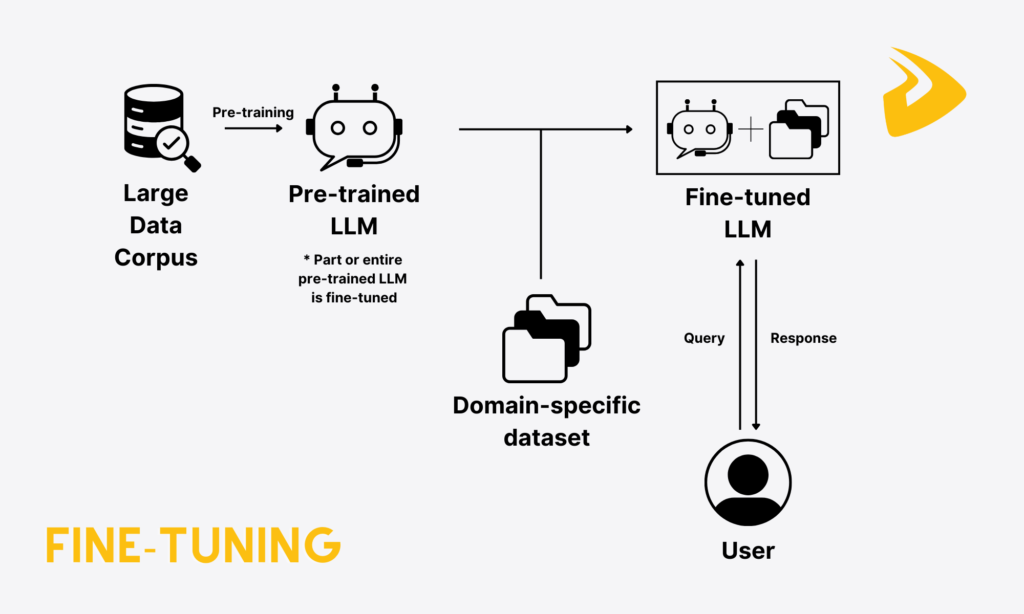
Suppose an operations team must convert varied customer messages into one approved set of issue labels. A clear prompt with examples may already work. If it keeps confusing two important labels, the team can prepare reviewed examples of those edge cases and test a fine-tuned model. Success means fewer errors on unseen messages, not merely better performance on the training examples.
Representative data matters more than a large pile of similar samples. Training examples need to cover ordinary inputs, difficult cases, and the distinctions the team cares about. Reviewers should agree on the correct target responses. Separate held-out examples must be kept for evaluation. If the data contains inconsistent labels, training may reinforce that inconsistency rather than fix it.
Microsoft’s fine-tuning overview describes improvements in format, style, and task performance as possible benefits, but says they need held-out evaluation. Model support and available training methods also vary. Teams should confirm that their chosen provider supports the intended training method before collecting a large dataset.
Before training, try a stronger baseline. Specify the output rules, show a few good examples, and test whether structured output controls already meet the requirement. Our prompt engineering best practices explain how clear instructions and example outputs can improve results without changing model weights. If those simpler methods work reliably, fine-tuning adds work without proving extra value.
Fine-tuning is not a dependable way to keep a product catalogue or policy library current. A model may absorb details from its examples, but it cannot verify that they are still valid at request time. For teams unfamiliar with the training workflow, our guide to training an AI model explains how to define the task, prepare data, and assess whether training is necessary.
Combine RAG And Fine-Tuning Only When Both Solve A Proven Gap
A hybrid RAG and fine-tuning approach makes sense only when the app needs both live knowledge and learned task behavior. The retrieval system supplies the relevant facts. The fine-tuned model handles a specific output pattern or improves its use of retrieved evidence. Building both before measuring the gaps makes the system harder to explain and maintain.
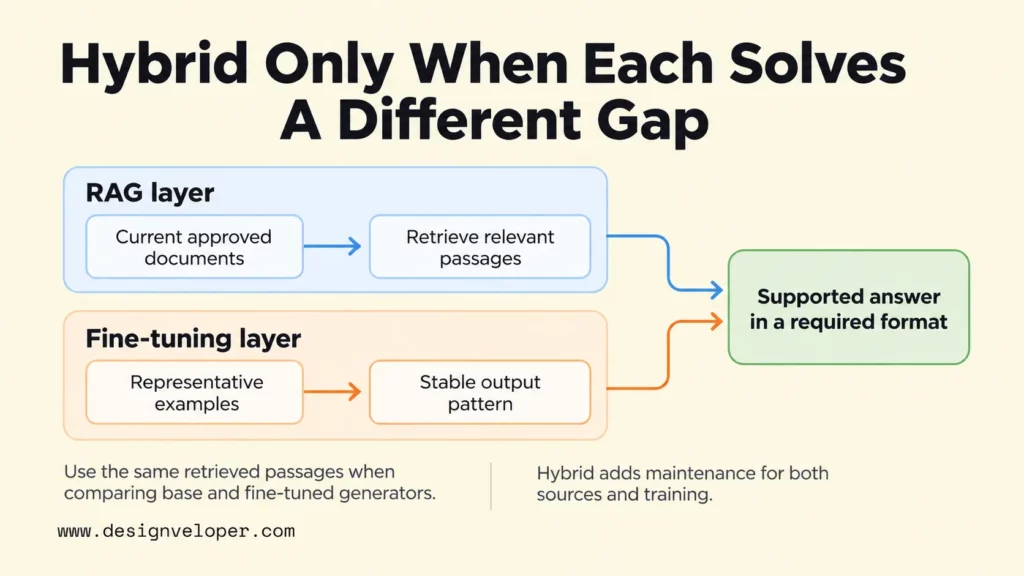
Consider an illustrative product-support workflow. The assistant retrieves the current installation instructions for a device. It must then produce a fixed troubleshooting record with an issue category, approved next step, and linked evidence. If the base model uses the correct documents but repeatedly breaks the required record structure, a fine-tuning experiment may be reasonable. Retrieval still handles changing instructions; training targets the repeated formatting failure.
Keep the two parts of a hybrid system separate enough to operate safely. Retrieval should supply authorized passages and their source identifiers to the generator. Fine-tuning can shape how the model uses that material, but training does not refresh the sources. An index update and a model update should each trigger their own tests. When comparing the base and fine-tuned generators, give them the same retrieved passages. That helps isolate changes in model behavior from changes in retrieval.
There is research support for testing this combination, but not for assuming it always wins. A Microsoft Research agriculture case study reported gains from fine-tuning and further gains from RAG in its particular experiments. Those findings concern its datasets and models. They are not general accuracy estimates for an enterprise chatbot.
A hybrid also creates two maintenance paths. Someone must refresh and secure the source collection. Someone must curate examples, rerun training when needed, and watch for behavior changes after model updates. The system has more points of failure and more work to evaluate. Choose the hybrid only if the measured improvement is important enough to justify that continuing effort.
Choose With A Test Set, Not A Rule Of Thumb
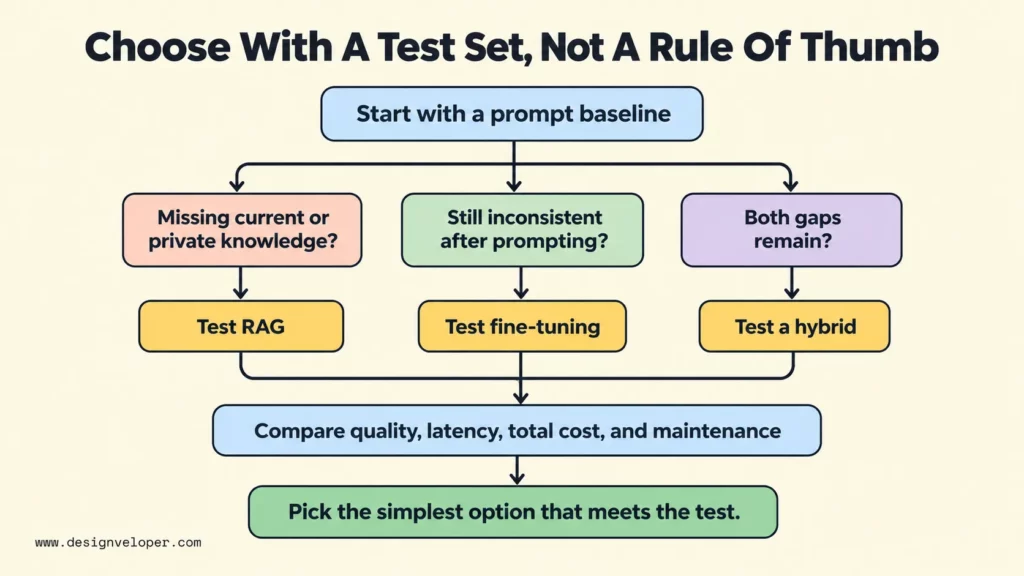
The most defensible way to choose between RAG and fine-tuning is to test the same real tasks under each relevant approach. Start with an unmodified model and a well-written prompt. Record what fails, then add only the capability that addresses that failure. This creates an evidence-based decision rather than a preference for one architecture.
Build the test set before choosing the solution. Collect representative user questions or inputs and define an acceptable answer for each. Include routine tasks and difficult cases. For a knowledge assistant, also include requests with no supported answer and questions involving restricted documents. For a classification tool, include ambiguous labels and inputs that were not used during training.
Meanwhile, for a finance assistant, the test set might include a current spending question, a request for an expense in a fixed format, and a question about another user’s records. Run the same relevant requests against the prompt-only baseline and each candidate approach. Set acceptance thresholds for supported answers, format validity, blocked unauthorized access, response time, and total cost before reviewing the results. Score retrieval quality only for candidates that use retrieval.
- Measure a prompting baseline. Use the same base model, clear task instructions, and relevant examples. Record answer quality, response time, and cost per completed task.
- Test RAG for knowledge gaps. If the baseline lacks current or private facts, add approved sources. Measure whether retrieval finds the expected documents and whether answers stay faithful to them.
- Test fine-tuning for behavior gaps. If output quality remains inconsistent after prompt improvements, train on representative examples. Compare the result against held-out tasks, not the training set.
- Compare operating trade-offs. Check response accuracy, source support or format compliance, latency, security controls, and the full costs of running and maintaining each option.
- Try a hybrid only when needed. Combine the methods if the single-method tests leave different important failures and the combined version measurably improves the required outcomes.
Each metric should match the job. A document assistant needs correct source selection, supported answers, and a safe response when evidence is missing. A classification system needs agreement with reviewed labels, including on unusual inputs. Both need acceptable speed and operating cost. Microsoft’s RAG evaluation guidance distinguishes retrieval quality from response relevance and groundedness. That separation helps teams locate a fault before changing the architecture.
Cost comparisons also need a shared unit. Estimate total monthly spending for the same workload, including document ingestion, search, model calls, training jobs, hosting, and human review. Include the time required to keep policies current or training examples accurate. Microsoft’s fine-tuning cost guidance confirms that training and serving can create separate charges. Exact rates depend on the model and deployment, so a single generic price would mislead.
For a first production pilot, we recommend recording expected sources, correct answers, and failure conditions before debating tools. In our RAG best practices guide, we explain why retrieval and answer quality need distinct checks. The same habit helps a broader LLM decision: it shows whether the next investment should improve data access, output behavior, or neither.
Make the final choice from the test results. Choose RAG when it closes a knowledge gap with acceptable source quality and cost. Choose fine-tuning when it produces a meaningful improvement in a stable task. And choose both when the combined version outperforms simpler options enough to cover its extra maintenance. If the baseline already meets the required standard, keep it and spend the saved effort on monitoring.
Also published on

Share post on




Related Articles


AI Proof Of Concept Development: How To Test Before You Scale
AI Proof Of Concept Development: How To Test Before You Scale Published October 22, 2026
LLM Deployment Pipeline: Stages, Testing, And Production At Scale
LLM Deployment Pipeline: Stages, Testing, And Production At Scale Published October 20, 2026
AI Model Monitoring: Metrics, Drift, And Production Reliability
AI Model Monitoring: Metrics, Drift, And Production Reliability Published October 20, 2026